Most of us are sick of tapping the screens and digging through menus just to do simple tasks on our phones. Honestly, just talking to your device is way faster. Voice AI has blown past the “gimmick” phase and is now changing how mobile apps actually work. Everyone wants hands-free control while they’re out running errands or driving, so developers are rushing to wire audio tech into their code. Before diving into the technical mechanics, we need to map out the foundational shifts and architectural decisions required to bring conversational features to life. Here is the complete breakdown of how to plan, build, and scale voice integration within modern mobile software.
1. Moving Beyond Rigid Text Input
Traditional touch interfaces belong to the past. Developers are finally moving away from rigid mobile design habits because people want hands-free control. For years, software depended entirely on glass screens. Users had to tap tiny icons, swipe across endless carousels, and squint at cramped keyboards. But tapping a screen becomes a real hassle when your hands are full of groceries, heavy packages, or when you are trying to navigate through busy city streets.
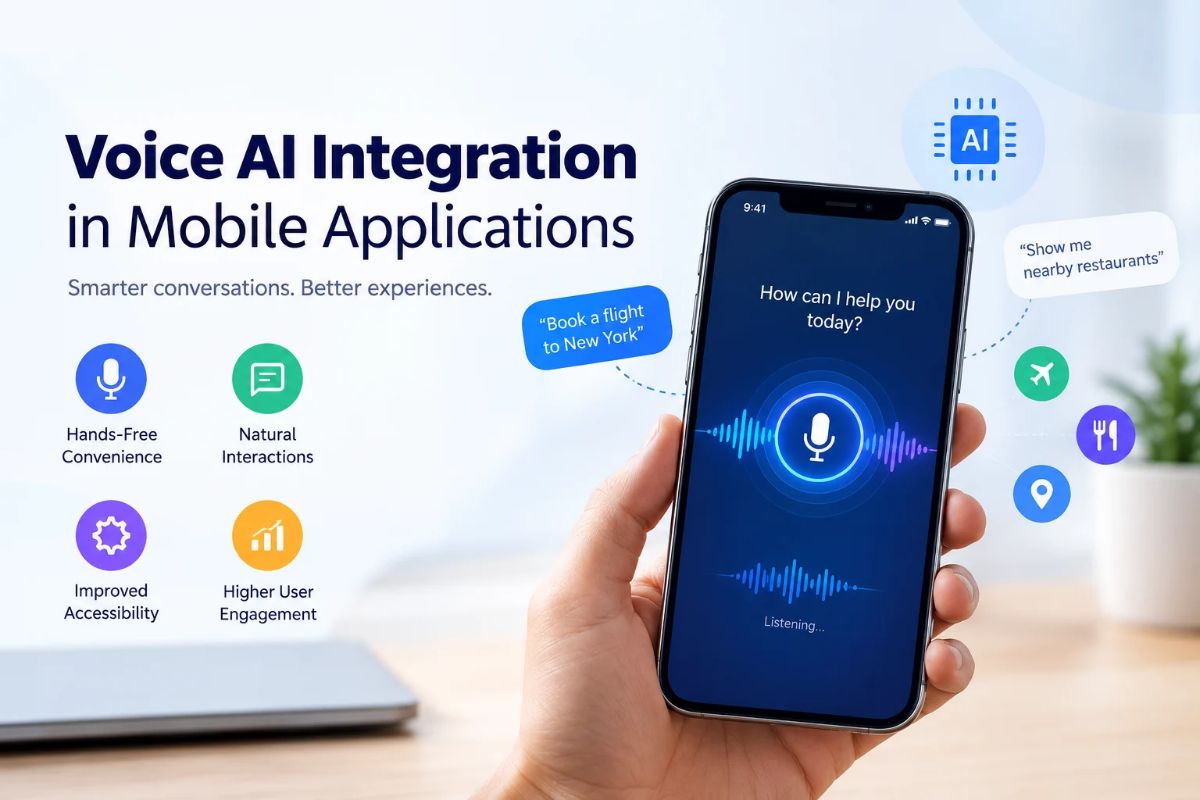
Voice-driven systems completely eliminate that frustration. Instead of digging through endless menus, people can just say what they want. When someone talks to a device, it captures the sound, turns it into text, and figures out the goal in a split second. Software shifts from a cold, transactional utility into a natural conversation, raising the bar for everyday convenience.
2. Choosing Your Architectural Foundation
Moving past basic screen interactions means engineering teams have to decide right away where all that heavy data processing actually happens. Getting this structural setup right dictates the entire performance ceiling of your app and shapes how data flows through your system.
Some development squads rely entirely on cloud-centric processing to solve this, capturing audio locally and pushing streams over internet connections to massive server clusters. While this delivers immense computational depth for complex multi-turn conversations, it introduces network lag and breaks down entirely when cellular coverage drops. Alternatively, edge-centric processing handles computation directly on smartphone processors or dedicated neural hardware, ensuring instant response times and absolute data privacy since audio never leaves the device. However, strict local storage limits and battery drain present ongoing optimization hurdles.
Because of these trade-offs, modern high-performance applications often lean toward a hybrid orchestration model that bridges both worlds. A lightweight, on-device trigger listens passively for specific wake words and handles basic offline shortcuts, while advanced queries route securely to the cloud. This blended setup bridges the gap between speed, resource conservation, and conversational depth.
3. Breaking Down the Mobile Audio Pipeline
Once your hybrid architecture is locked in and operational, orchestrating a reliable voice command shifts from high-level system planning down into the precise mechanics of the mobile audio pipeline. To ensure data flows seamlessly from physical hardware into actionable software logic, every single stage within this processing chain must operate in absolute harmony without dropping a single packet.
Audio Acquisition and Front-End Cleaning
It all starts at the phone’s microphone. That tiny piece of hardware catches your voice, but it also picks up everything else happening around you—like street noise, gusty wind, and echoes bouncing off walls. Before the software can make sense of what you said, the raw audio has to get scrubbed. Signal filters step in to strip away background hums, cut out feedback, and level out the volume so the app gets a crisp, usable recording.
Automatic Speech Recognition
With a clean audio file ready, the data feeds straight into the speech recognition engine. This part of the software uses neural networks to match spoken sounds up with written words. It has to handle this translation right on the phone’s chip quickly, making sure it keeps up with normal speaking speeds without missing words or stuttering.
Intent Parsing and Dialog State Management
Turning speech into text is only the first step. To actually do what the user wants, the words flow into intent parsers and dialog managers. A smart dialog manager remembers what was said a moment ago so a conversation flows naturally. If you ask about the weather outside and then follow up by asking about the weekend, the system holds onto the location you mentioned first, saving you from having to repeat yourself.
4. Solving Real-World Engineering Hurdles
Managing that continuous stream of data introduces severe real-world engineering hurdles that do not exist in desktop or web environments.
Minimizing latency is chief among them to keep the conversation smooth, as users notice processing delays exceeding four hundred milliseconds, which instantly shatters the illusion of natural conversation. At the same time, managing power consumption is critical since continuous microphone listening can drain a battery rapidly if engineering teams do not rely on low-power hardware interrupts and optimized wake-word detectors.
Furthermore, because mobile hardware varies widely across thousands of manufacturers, rigorous testing across numerous device profiles is required to ensure consistent transcription accuracy for every user. Finally, because voice data contains sensitive biometric markers, securing data streams in transit, anonymizing logs, and adhering to strict regional privacy regulations remain non-negotiable pillars of production deployment.
5. Step-by-Step Implementation Blueprint
Translating these privacy and performance principles into a working product requires a disciplined, step-by-step implementation blueprint to keep development cycles organized.
| Phase | Core Objective | Key Technical Actions |
| Phase 1: Workflow Auditing | Identify friction points | Locate repetitive typing tasks, search boxes, or complex forms where voice input adds clear value. |
| Phase 2: Framework Selection | Choose audio libraries | Compare native operating system APIs against cross-platform plugins and third-party AI toolkits. |
| Phase 3: Front-End Configuration | Establish audio hooks | Request microphone permissions, configure sample rates, and set up real-time noise reduction filters. |
| Phase 4: Fallback Design | Plan for recognition errors | Build visual text inputs and clear error states for situations where background noise disrupts speech parsing. |
| Phase 5: Performance Testing | Measure real-world metrics | Monitor memory footprints, battery draw, and transcription accuracy across target mobile handsets. |
6. Industry Applications and Use Cases
Executing that implementation blueprint successfully allows companies to deploy conversational audio across multiple consumer sectors as mobile ecosystems mature.
In retail and e-commerce, buyers discover items, filter catalogs, and complete purchases using spoken phrasing, resulting in faster checkouts and lower cart abandonment rates. In banking and finance, account holders check balances, transfer funds, or review recent transaction histories while on the move, protected by secure voice biometric verification.
Meanwhile, health and fitness platforms allow users to log dietary intake, schedule clinical check-ups, or track exercise metrics hands-free during active workouts, while field operations technicians record inventory notes and query system manuals without taking their hands off physical tools.
Conclusion
Integrating voice capabilities into AI mobile software represents a fundamental evolution in how people interact with technology. Moving beyond tedious screen taps into fluid, speech-driven workflows allows engineering teams to deliver faster, more accessible, and profoundly intuitive digital experiences. However, achieving low latency, robust noise handling, and scalable system architecture demands specialized technical execution.
If your organization is ready to introduce advanced voice features into your mobile applications without struggling through complicated infrastructure setup, Devherds provides the ideal partnership. We deliver expert mobile engineering, custom AI integrations, and high-performance system design tailored to accelerate your product timeline.
Ready to transform your mobile app with professional voice AI integration? Connect with us today to arrange your technical consultation and take the next step forward.